Smart Inventory Record Inaccuracy (IRI) Prediction and Management
Foreword
Our previous reports have called out the scale and nature of the problem of wrong inventory records. In this new report, we aimed to go further by asking a simple but important question: can retailers move from merely identifying inventory record inaccuracy to predicting where it is most likely to occur and acting on it sooner?
The findings presented here suggest that they can. Across a large multi-retailer evidence base, the research shows that a substantial share of stock record errors is predictable and that this insight can be used to target counting effort far more effectively.
Perhaps most importantly, the report highlights that not all inaccuracies carry the same risk. Phantom Inventory, where systems show stock that is not physically present, remains one of the most damaging problems because it suppresses replenishment and leads directly to lost sales. The research shows that these high-risk cases can be identified much more effectively when retailers use data intelligently.
The implication is clear: stock counting should not disappear, but it should become smarter. Retailers should use these findings to prioritise effort, focus more attention on volatile and less predictable categories, and test prediction-led triage in a controlled way. The opportunity is not simply to count less, but to count better, improve availability, and make better use of scarce store resources.
I would like to thank Professors Glock, Rekik and Syntetos for carrying out this research, and the retailers who helped contribute to the thinking and the findings presented in this report.
As with all the research undertaken on behalf of ECR Retail Loss, it would not be possible without the active support and involvement of the retail community and the many employees who generously gave their time to participate in such a meaningful way. Thank you for taking the time to share your thoughts and experiences. By working together, we are much more likely to Sell More and Waste Less.
Finally, I encourage you not only to read and share this study, but also to read an accompanying report introducing a maturity model that can act as a road map for organisations as they seek to tackle the IRI problem and unlock lost sales potential.
John Fonteijn
Chair, ECR Retail Loss
Executive Summary
Inventory record inaccuracy (IRI) – the gap between what is physically present in the store and what the system believes is in stock – quietly erodes sales, absorbs scarce labour, and distorts replenishment decisions. Previous ECR research shows that correcting inventory records leads to sales uplifts of roughly 4 to 8%, with the largest gains on fast movers and high-discrepancy items. Retailers invest heavily in stock counts to find and fix IRI. But what if we could predict which items will be inaccurate before anyone touches them?
This ECR project provides strong evidence that prediction has the potential to revolutionise the management of stock records. Using a multi-retailer evidence base of more than 1.3 million stock-audit observations across six grocery retailers, we show that a transparent, explainable machine learning framework can identify likely inaccuracies with promising and operationally useful accuracy – and for predictably behaving items, estimate the sign and size of errors within a narrow tolerance.
The central finding is that a large and operationally meaningful share of grocery SKU-store records is predictable under our realistic modelling framework. Depending on the retailer and category, between 51% and 84% of items at any given retailer behave consistently enough that the model can often forecast whether a discrepancy exists and, for a subset of predictable items, estimate its size well enough to support prioritisation and, in some cases, low-risk correction without an immediate physical count. For this predictable group, 60 to 81% of proposed corrections are exactly right, and 75 to 93% are within one unit of the true figure.
An equally important insight is that not all categories should be managed in the same way. The research shows that some categories – particularly fresh, short-life, and process-intensive lines – are inherently less predictable. This is operationally significant: these categories should not be seen as model failures, but as priority targets for more frequent physical counts. In other words, prediction creates a better division of labour: stable categories can be safely deprioritised, while less predictable categories receive more audit attention, helping retailers protect on-shelf availability and recover sales where the risks are highest.
The daily output is a concise, explainable triage list that lets store teams spend minutes – not hours – on the right SKUs, while statutory stocktakes remain the governance anchor. We translate the findings into a practical operating model: a day-to-day routine that clarifies who does what, when, and how change should be governed.
IRI management and the stock counting business are likely to change materially in the coming years. The evidence in this report – across six retailers and multiple operating conditions – shows why prediction-led triage deserves serious managerial attention, and how it can be deployed safely alongside conventional audit governance.
These findings should be interpreted with appropriate operational caution. Performance varies by retailer, category, and data quality; fresh and process-intensive categories remain harder to model; and the economic value estimates reported here are model-based rather than direct measures of realised sales uplift. For these reasons, a disciplined pilot remains the appropriate next step before scale deployment.
Headline Results Across Six Grocery Retailers
- Between 51% and 84% of SKU-store records qualify as predictable on any given day.
- 60 – 81% of proposed corrections are exact; 75 – 93% fall within ±1 unit.
- Targeted auditing surfaces the large majority of absolute IRI while reallocating 37 – 56% of counting effort toward higher-value checks.
- Range-1 accuracy (the share of records falling within ±1 unit of physical stock) is the most operationally meaningful metric – retailers may be able to deprioritise around half of all SKUs from immediate audit, subject to governance rules and category-specific tolerances.
- Phantom Inventory is detected with strong performance in our data and appears to be the highest-value target for intervention.
- Deep-dive analysis on one retailer demonstrates that reallocating the same daily counting budget toward model-ranked items delivers a +362% increase in expected net economic value per audit (model-based estimate; field pilot required for realised uplift).
Glossary of Key Terms
TermDefinition
| Inventory Record Inaccuracy (IRI) | The gap between the quantity of an item that is physically present in the store and the quantity the computer system believes is in stock. IRI = Physical stock − System stock. |
| Physical Zero (PZ) | A situation where the physical stock of an item counted in store is zero – regardless of what the system shows. When PZ occurs and the system shows positive stock, this becomes Phantom Inventory. |
| Phantom Inventory (PI) | A situation where the system records positive on-hand stock for an item, but there is nothing physically on the shelf or in the backroom. The system ‘believes’ the product is available when in reality the shelf is empty. This blocks replenishment, creating a hidden stockout. Note on terminology: in some retail environments, “PI” is used for partial or perpetual inventory, and the term phantom stock is preferred for the case described here. In this report, PI refers exclusively to the system-shows-positive / shelf-is-empty condition. |
| Stock Record Accuracy (SRA) | The proportion of SKU-store records where the system stock matches the physical count (within a defined tolerance). |
| Range-1 Accuracy | A practical accuracy measure that treats a record as accurate only when the absolute discrepancy is one unit or less (±1 unit, i.e., |IRI| ≤ 1). More relevant operationally than simple binary accuracy, as it filters out trivial differences while catching important errors. |
| Predictable SKU | A SKU is treated as predictable only when two conditions are met: (1) the expected discrepancy remains within a retailer-defined tolerance band; and (2) the model’s intermediate signals are internally consistent. If either condition is not met, the item is routed to human verification rather than being auto-corrected. |
| Ensemble Learning | A machine learning approach that combines the outputs of multiple models to achieve higher accuracy than any single model alone. The staged pipeline in this study uses ensemble methods at each stage. |
| SHAP Analysis | A technique from explainable AI that quantifies each input variable’s contribution to a prediction. Used here to produce plain-language reason codes explaining why an item was flagged. |
| Cycle Count | A targeted stock count of a selected subset of items in the store, typically performed daily or weekly. |
| Full Inventory Audit | A comprehensive count of all items in the store, typically performed less frequently (monthly, quarterly, or annually). |
| SKU (Stock Keeping Unit) | A unique identifier for each distinct product and packaging variant held in the store. |
Introduction
Retailers operate two inventories: the system inventory and the physical stock. When these diverge, losses compound silently. If the system overstates reality – recording more stock than actually exists- replenishment is not triggered even though shelves are empty. If it understates, orders fire prematurely, capital hides in the backroom, and planning noise increases. This divergence – inventory record inaccuracy (IRI) – is a structural feature of day-to-day retail operations, not an occasional anomaly.
Foundational research shows that IRI is pervasive and economically material. Inaccuracy rates between 33 and 80% have been documented across the industry, with grocery stores often exceeding 60% [1, 2, 3]. IRI arises from multiple overlapping causes: shrinkage (spoilage, theft), transaction errors (mis-scans, unit-and-pack mistakes), and misplacements (items stocked in the wrong location or stranded in the backroom) [4]. Organisational choices – how often items are counted, how staff is allocated, and how disciplined store processes are – shape both how errors are created and how quickly they are corrected [5].
The most damaging form of IRI is Phantom Inventory (PI): the system records an item as available, but the shelf is physically empty. Because the system ‘sees’ the item as in stock, no replenishment order is triggered. The shelf stays empty, customers walk away, and the problem persists until someone physically investigates. Unlike a simple counting error, Phantom Inventory silently blocks the supply chain – and research consistently links it to lost sales and customer frustration [6]. Our consortium data shows that among SKUs affected by PI, the model identifies 83% of cases, and even the items incorrectly flagged tend to be at very low stock levels, making the check worthwhile regardless.
While Phantom Inventory is the most damaging error pattern for on-shelf availability, the opposite case – positive IRI, where the system understates physical stock – is not benign either. On perishable lines it inflates on-hand assumptions, suppresses timely replenishment of fresh receipts, and accelerates waste, with knock-on effects on expiry dates reaching the customer [7]. Both error signs therefore matter, though through different mechanisms.
The dominant fix remains physical verification: full stocktakes, cycle counts, and ad-hoc checks. While effective, counting is labour-intensive, disruptive, and cannot be applied to every SKU as assortments grow and store teams shrink. The key managerial question therefore becomes: which items should we count today? Rather than counting everything a little, retailers need to count the right things a lot.
Modern retailing makes this harder. Broader assortments, faster promotions, shorter product lifecycles, and tighter labour all erode the traditional approach of blanket counting. But they also create an opportunity: the same operational data that generates IRI – sales records, replenishment logs, audit trails, system stock positions – contains signals that allow us to predict where discrepancies are building before we go and look.
This is precisely what we study in this report. Can we predict IRI? And if so, how do we turn those predictions into practical daily decisions? Across the participating retailers, we show that IRI is predictable for a substantial and operationally meaningful subset of SKU-store records, provided the modelling and deployment process is designed with appropriate leakage controls, calibration, and governance.
The remainder of this report is organised as follows.
Section 2 describes the data and methodology. Section 3 presents consortium-level results, showing that accepting one unit of error as accurate (Range-1 accuracy) has important positive operational implications. Section 4 provides a deep dive on capacity, economic value, and explainability. Section 5 is the operationalisation playbook. Section 6 concludes with implications and the path forward.
ECR Retail Loss also runs inventory record accuracy training where the three Professors look at practical implications of their research. You can read a summary of the 2026 IRI Training course here.
What This Report Delivers
- A transparent, staged machine learning framework tested across six grocery retailers.
- Consortium-level evidence that most grocery IRI is predictable – with robust accuracy across diverse retail formats.
- A practical operationalisation playbook: the daily triage routine, role responsibilities, tolerance bands, and a 90-day deployment path.
- A deep-dive analysis demonstrating capacity-constrained prioritisation, economic value.
Data and Methodology
The Retail Panel
Our study draws on a four-year panel of real retail operations, covering more than 1.3 million stock-audit events collected between May 2018 and April 2022 across six grocery retailers. The retailers participating in our study are described in Table 1. To protect commercial confidentiality, participating retailers are anonymised as Retailers A through F.
The panel spans retailers ranging from national chains operating a few dozen stores with tens of thousands of SKUs, to larger players with over eighty outlets. The panel intentionally mixes mainstream and discount formats to reflect operating heterogeneity – different countries, store formats, assortment widths, and audit policies.
To mirror real-world decision-making and avoid any information leakage, the panel is split strictly along the time dimension into training, validation, and a held-out test set. All results reported in this white paper are drawn exclusively from future periods the models had not seen during training.
This forward-looking design is implemented within store-SKU histories and combined with time-consistent out-of-fold stacking and validation-only probability calibration. Readers seeking a non-technical explanation of how the training, validation, and test sets were designed to reflect real-world decision-making can find a practitioner-oriented overview in Appendix D.
This matters because the managerial question is not simply whether a model fits historical data. It is whether the model can rank tomorrow’s audit candidates better than current practice, under realistic labour constraints and with acceptable governance risk. The deeper methodological detail is provided in appendices A – C rather than crowded into the main narrative.
Table 1: Participating retailers. The panel includes a mix of mainstream and discount formats.
RetailerFormatStoresSKUs
| A | Grocery | 30 | 33,963 |
| B | Grocery | 30 | 154,617 |
| C | Grocery | 84 | 137,219 |
| D | Grocery | 30 | 36,127 |
| E | Grocery | 27 | 194,927 |
| F | Grocery | 30 | 14,596 |
How the Prediction Pipeline Works
The evidence reported here rests on a forward-looking empirical design intended to mirror deployment conditions. Features are built from data available before each audit only; physical counts, discrepancy labels, and post-audit corrections are excluded from prediction inputs by construction. Upstream model outputs are passed downstream through time-consistent out-of-fold meta-features, and key probabilities are calibrated on validation data rather than on the held-out test periods.
A straightforward application of machine learning on raw operational data does not produce satisfactory accuracy. Early trials using a single algorithm confirmed this: predictions were too noisy and too imprecise to be operationally useful. The problem is inherently difficult – IRI distributions are skewed, error patterns differ across products and stores, and the consequences of a wrong correction can be worse than no correction at all. We therefore developed a staged ensemble learning approach that builds confidence progressively before proposing any action (1).
Stage 0: Data Preparation and Feature Engineering
Each observation represents what happens for a given item in a given store between two consecutive stock audits. We assemble around 36 variables from six families: inventory state and discrepancy history, sales and stock movements, price and promotion context, audit cadence, product attributes, and store characteristics. All features use only information available before the audit – physical counts and post-audit corrections are strictly excluded, so the model only sees what a decision-maker would see at prediction time.
Stage 1: Building Weak Predictors via Ensemble Learning
Rather than predicting IRI directly, Stage 1 deploys an ensemble of simpler models that each tackle one piece of the puzzle: identifying extreme discrepancies early, categorising errors by broad magnitude range, and flagging whether a discrepancy is positive or negative. If we build and combine multiple models in this way, the predictors in the staged pipeline produce mutually consistent signals rather than conflicting indications about the likely error pattern.
For this predictable set, regression models estimate the signed magnitude of the discrepancy. This supports automatic or semi-automatic correction: when the predicted discrepancy falls within the authorised tolerance band and the signals remain internally consistent, the system can propose or apply a correction without a physical count. Items that do not meet these conditions are routed to human auditing, so automation is reserved for cases where the model’s evidence is sufficiently coherent and operationally safe.
The Three-Lane Daily Triage
- Lane 1 – Auto-adjust: Predictable items with a confident, low-risk correction within department tolerance.
- Lane 2 – Quick verify: Predictable items near a threshold or showing unusual signals – a brief check suffices.
- Lane 3 – Count now: All non-predictable items, plus any item flagged as Physical Zero or Phantom Inventory.
Results Across Six Retailers
The Diagnostic Picture: IRI in Practice
Before applying predictive models, we examined the state of inventory records across all six retailers (see Table 2). The picture is consistent and sobering: IRI is both common and large enough to cause real operational harm. Initial diagnostics reveal heterogeneous IRI distributions.
Some retailers (A, B, D) show IRI values tightly clustered around zero. This pattern is consistent with relatively stable records, but it can also reflect counting regimes that systematically under-detect certain error types (for example, low cadence, narrow scope, or category exclusions). The two interpretations cannot be cleanly separated from audit data alone, and we therefore present the consortium results as descriptive rather than as a ranking of process quality.
Others (C, E, F) show strong outliers, with discrepancies reaching tens of units.
Retailer E displays systematically positive IRI – the system consistently understates physical stock, indicating a different pattern of process weakness from the overstatement issues seen elsewhere.
Overall, nearly 60% of all audited SKU-store combinations are inaccurate, with errors roughly split between negative gaps (the system overstates physical stock, at 32%) and positive gaps (the system understates, at 28%). This matters because negative and positive errors behave differently over time: negative gaps accumulate steadily between audits – creating service-killing deficits that compound with every passing day – while positive errors tend to remain comparatively stable in count terms but carry their own operational cost on perishable lines, where overstated on-hand suppresses fresh replenishment, deteriorates available expiry dates, and increases write-offs. Waiting for a scheduled count therefore means both the most damaging deficits and the slowest-burning waste exposures have the longest to grow.
Stock accuracy varies significantly across the six retailers. Under a simple binary definition (2) (exact match between system and physical), accuracy ranges from 29% to 50%. Under Range-1 (discrepancy within one unit), it ranges from 51% to 71%.
The gap between these two measures is itself revealing: many items counted as ‘inaccurate’ under binary counting carry discrepancies of only one unit – often trivial in operational terms. Range-1 filters this noise and focuses attention on the items that genuinely need intervention.
Table 2: Baseline stock accuracy and IRI characteristics by retailer (before prediction). Binary accuracy = exact match; Range-1 = discrepancy within ±1 unit.
RetailerBinary AccuracyRange-1 AccuracyMean |IRI|Mean IRI (signed)
| A | 47% | 71% | 2.5 | −0.4 (slight overstate) |
| B | 45% | 61% | 4.1 | −0.9 (overstate) |
| C | 29% | 52% | 26.6 | −5.1 (strong overstate) |
| D | 50% | 68% | 12.2 | −0.4 (slight overstate) |
| E | 36% | 51% | 23.9 | +1.6 (strong understate) |
| F | 35% | 52% | 10.2 | −0.9 (overstate) |
Audit frequency is not standardised across the industry. Some retailers count biannually or annually (A, D, E); others count monthly, weekly, or at higher frequency (B, C, F). This variation matters because the longer the gap between audits, the more time discrepancies have to accumulate. The data confirms that Phantom Inventory incidence grows with the audit interval: rates rise from around 18% with monthly counting to over 27% with biannual audits.
Primary Finding: Range-1 as the Operational Threshold
The most important practical output of this research is the identification of Range-1 accuracy as the correct operational lens for IRI management. Unlike binary accuracy – which simply asks whether any discrepancy exists – Range-1 focuses on discrepancies large enough to matter: those exceeding one unit in absolute terms.
Why does this distinction matter? A one-unit discrepancy in a high-volume fast mover is trivial; the same discrepancy in a promoted line with a two-unit reorder point can trigger an unnecessary order or suppress a necessary one. By focusing on Range-1, retailers concentrate audit effort on items where inaccuracy is operationally consequential, while safely deprioritising items where the record is close enough to reality. ±1 is just our reporting standard, not the rule applied in stores. The tolerance tightens toward an exact match for low-reorder-point or high-value items – where one unit can make or break an order – and loosens for large pack sizes. Deployment uses the per-department tolerances in §5.3, not a single ±1 threshold.
The results across the consortium, illustrated in Table 3, suggest that Range-1 prediction may allow retailers to deprioritise around 40 – 50% of their assortment from immediate audit, subject to governance rules, category-specific tolerances, and pilot validation. At Retailer D, for example, 68% of SKUs fall within Range-1, above the consortium’s 40–50% range, reflecting Retailer D’s comparatively stable records. This suggests that they may be deprioritised for immediate auditing under an appropriate control framework, removing roughly two-thirds of the immediate audit workload without compromising availability where it matters.
The same Range-1 logic applies consistently across Retailers B, C, E, and F. This should be understood not as a reduction in control, but as a reallocation of the same audit resource toward the items that actually need attention.
Table 3: Aggregated prediction accuracy across six grocery retailers. ★ denotes the recommended primary operating metric.
Prediction TargetAvg. AccuracyMinMaxPredictable SKU Share
| Range-1 (|IRI| ≤ 1 unit) ★ | 82% | 76% | 88% | 51 – 84% |
| Range-2 (|IRI| ≤ 2 units) | 85% | 79% | 91% | 51 – 84% |
| Binary IRI (any discrepancy) | 84% | 80% | 89% | 51 – 84% |
| Physical Zero (PZ: stock = 0) | 83% | 78% | 87% | 51 – 84% |
| Phantom Inventory (PI) | 81% | 77% | 86% | 51 – 84% |
The precision-recall trade-off is central to deployment (3). The trade-off under concern governs the percentage of false versus true identifications. At Retailer B, for instance, the binary classifier achieves 81.5% overall accuracy: 35.4% true positives (inaccurate items correctly flagged), 46.1% true negatives (accurate items left untouched), 9.7% false positives (accurate items that nevertheless are flagged as inaccurate), and 8.7% false negatives (inaccurate items that are missed). At Retailer F – where IRI is more prevalent – the model is even more powerful: 56% true positives, 28% true negatives, and a similarly low 7% false negative rate. In both cases, the false positives are not wasted effort: items flagged but found accurate tend to be at very low stock, making the check operationally worthwhile. The model makes the precision-recall trade-off explicit and configurable, rather than hiding it inside blanket counting rules.
Phantom Inventory: The Highest-Priority Target
Among all forms of IRI, Phantom Inventory (PI) demands the most urgent attention. When a product shows as available in the system but is physically absent, replenishment is silently suppressed. Staff and systems alike believe the item is fine. It is not – and the gap translates directly into lost sales, frustrated customers, and wasted labour when the problem is eventually discovered.
The data confirms both the prevalence and the trajectory of Phantom Inventory. Across the consortium, PI affects between 8% and 24% of items at any given audit. The rate grows with time between counts: retailers who leave long gaps find progressively more PI when they do check. At Retailer F, for example, around 24% of SKUs are affected by Phantom Inventory at any given audit – and the model correctly identifies 83% of these cases. Among items flagged by the model, 14% are false positives – items incorrectly identified as PI – though (and as discussed above) stock levels in these cases are typically very low, making the check operationally worthwhile regardless. Of the true PI cases, only 4% escape detection entirely (false negatives).
At Retailer E, Phantom Inventory incidence rises from approximately 18% with monthly audits to 27% with biannual audits, illustrating the compounding cost of infrequent counting. Frequent, targeted checking of high-risk items appears operationally important for availability management.
Why Phantom Inventory is the Highest-Priority Target
- It silently blocks replenishment – the system ‘sees’ stock that does not exist and never places the order.
- It persists until someone physically investigates – no automated system catches it without a count or a prediction.
- It grows with audit gaps – the longer between counts, the more Phantom Inventory accumulates.
- Even partial detection yields disproportionate benefits – one corrected PI record can unlock a full replenishment cycle and immediately recover lost sales.
Predictable vs. Non-Predictable SKUs
The second major finding is that the grocery assortment naturally divides into predictable and non-predictable items. Predictable items have stable, systematic IRI patterns the model can estimate with confidence. Non-predictable items show irregular, volatile patterns that resist modelling – and for these, traditional counting remains the right approach.
Table 4 shows that across the consortium, predictable items account for between 51% and 84% of the assortment, depending on the retailer and the category. For predictable items, regression models estimate the signed magnitude of IRI with strong accuracy: 60 – 81% of corrections are exactly right, and 75 – 93% are within one unit of the true value. Even Retailer F, the least predictable retailer in the panel at 51% sitting at the bottom of this range, still allows roughly half its audit effort to be reallocated away from blanket counting toward the items that need it.
The divide is not random – it reflects underlying product and process characteristics, and in particular the demand dynamics of each category. Stable, high-volume packaged goods with consistent replenishment cycles tend to be highly predictable. Fresh categories, short-life perishables, and items subject to frequent promotions or planogram changes are less predictable – because their demand patterns are inherently more volatile, making the relationship between system records and physical stock harder to model.
Table 4: Predictability and correction accuracy by retailer (A – F). Ranges reflect variation across categories within each retailer.
RetailerPredictable SKU ShareExact CorrectionWithin ±1 UnitKey Insight
| A | 74% | 76 – 82% | 91 – 94% | Strong ambient performance |
| B | 73% | 76 – 82% | 75 – 85% | Good across categories |
| C | 58% | 68 – 79% | 75 – 80% | Outlier-driven volatility |
| D | 75% | 75 – 80% | 90 – 93% | Stable records, compact range |
| E | 84% | 65 – 68% | 86 – 90% | Systematic positive IRI |
| F | 51% | 60 – 65% | 75 – 80% | Lowest predictability; audit-intensive |
Category-Level Variation
Predictability is strongly correlated with product department. Detailed analysis at Retailer A shows that categories with stable demand patterns – frozen (89% predictable), drinks (88%), and non-food listed (83%) – achieve the highest prediction accuracy, with perfect corrections exceeding 82% and corrections within one unit exceeding 93%. At the other end, fresh fruit and vegetables (66% predictable) and meat, poultry, and fish (90% predictable but with higher absolute IRI) reflect the impact of short shelf life and variable demand on record accuracy.
At Retailer E, the five least predictable categories are bake-off (10% predictable), eggs (36%), vegetables (54%), fruits (56%), and household goods (53%). These are precisely the categories where demand is most volatile and physical handling most error-prone. For these, the model explicitly routes items to human auditing rather than attempting an unreliable correction – an important safety feature of the framework. Across all other categories at Retailer E, predictability exceeds 84%, and model performance is materially stronger.
This category-level variation has a direct operational implication: the prediction system adapts its behaviour by product type. High-predictability ambient and frozen lines can be managed with automated or semi-automated corrections. Fresh and perishable lines should be counted more frequently and corrected by store teams. The model makes this distinction automatically, based on each item’s demand dynamics and error history.
This distinction is operationally important. Non-predictable categories are often those where demand is volatile, shelf life is short, handling is intensive, and stock errors are more likely to translate quickly into on-shelf unavailability. For these categories, increasing count frequency is not simply a control response; it is a sales-protection mechanism. The value of prediction therefore lies not only in identifying items that can be safely deprioritised, but also in revealing where additional counting effort is most likely to improve availability and prevent lost sales.
Taken together, these results support the use of model outputs as a prioritisation aid. They do not eliminate the need for retailer-specific governance, tolerance setting, and pilot validation.
Deep Dive: Counting Smarter, Not More
The consortium results demonstrate that IRI prediction works robustly across retailers and formats. To understand the full operational and commercial potential, we conducted a detailed analysis with one participating retailer – using over 2 million audit observations. This deep dive addresses three questions that matter for deployment: Does model-guided counting find more problems per audit trip? Is there measurable economic value? And can store teams understand why an item was flagged?
Finding More with the Same Effort
In practice, stores have a fixed daily counting budget: a set number of items that can realistically be checked. The question is whether model-guided selection finds significantly more problems per check than current practice.
The results, illustrated in Table 5, are directionally clear. When the model selects the top 5 items per store per day, 87.5% are genuinely inaccurate – nearly nine out of ten checks reveal a real problem. At a budget of 20 items per store-day, yield is still 76.3% while capturing nearly two-thirds of all inaccuracies. For Phantom Inventory specifically, selecting just 10 items per day captures 63.4% of all PI cases in the store.
Compared to the best non-model approach (ranking items by sales velocity, which is arguably one of the standard approaches used in retail industry), the machine learning guidance delivers approximately a 19% uplift in inaccuracy detection – gains concentrated exactly where they matter most: the small number of daily checks where every audit slot is precious.
Table 5: Model-guided audit yield at different counting depths (held-out test set, one retailer). Median budget = the median store’s daily audit capacity across the deep-dive sample.
Items Checked / Store-DayInaccuracy FoundAll IRI CapturedPI Captured
| 5 items | 87.5% | 25.7% | 47.9% |
| 10 items | 81.7% | 42.1% | 63.4% |
| 20 items | 76.3% | 62.7% | 78.7% |
| 40 items | 70.7% | 82.9% | 91.2% |
| 72 items (median budget) | 66.3% | 94.0% | 98.4% |
| 100 items | 65.0% | 97.0% | 99.7% |
The Economic Value of Counting Smarter
Beyond operational metrics, we translated performance into expected commercial value. The analysis combines two components: the margin saved by resolving Phantom Inventory (which blocks replenishment and causes lost sales) and the value of correcting large discrepancies (which distort ordering and handling).
These value estimates should be read as selection-adjusted expected value under a transparent baseline scenario, not as a claim of realised financial return. They are useful because they show how much better the same counting effort could be, but they do not replace retailer-specific pilots, which remain necessary to measure downstream sales, substitution effects, and actual replenishment response.
The key finding is directionally strong but should be interpreted carefully: holding daily audit effort constant, reallocating those same audits toward model-ranked items substantially increases expected net economic value per audit under the study’s baseline parameter assumptions. In the retailer deep dive, the median model-based uplift is +362% per audit, driven primarily by better targeting of Phantom Inventory rather than by a large increase in correction value on ordinary discrepancies.
As a validation, the same analysis applied to random item selection (a placebo) produces a uniformly negative result in every store – confirming that the value signal is not a statistical artefact of simple re-ranking. At the same time, these economic estimates remain model-based rather than realised sales outcomes; a matched field pilot is therefore the right next step for retailer-specific quantification.
What the Economic Analysis Means for Retailers
- You do not need more counting hours – you need smarter direction of the hours you already have.
- Phantom Inventory drives the vast majority of the commercial gain. Better PI detection is where the money is.
- The value signal is positive across the stores included in this analysis.
- A matched test-versus-control pilot (see Section 5.6) will quantify your specific uplift before full rollout.
Why Was This Item Flagged? Explainability
For store teams to trust and act on model outputs, they need to understand not just what was flagged but why. We used SHAP (Shapley Additive Explanations) analysis to decompose each prediction into the operational signals most responsible for it. (4)
The analysis reveals a clear hierarchy of drivers. Stacked meta-features from the ensemble pipeline contribute 38.2% of total predictive power – these capture the combined intelligence of the Stage 1 weak predictors and represent the model’s learned understanding of complex IRI patterns. Record stability features account for 21.5%: instability in the system stock record (frequent small adjustments, persistent negative values, or sudden jumps) is the single strongest individual signal family. Demand-side signals contribute 13.9%: high sales velocity relative to recent replenishment, or a mismatch between sales rate and stock position, flags items where discrepancies accumulate fastest. The remaining predictive power comes from audit timing and cadence (how long since the last count), promotional and price context, and product and store characteristics.
In the daily triage, each flagged item comes with a compact set of plain-language reason codes – for instance: ‘record unstable for 14 days, demand high, last audit 23 days ago.’ This transparency helps store teams prioritise root-cause investigation over routine fixes, and builds the confidence needed for teams to act without hesitation. The explanation is not a black box – it is a conversation starter between the model and the store.
Operationalisation: The Day-to-Day Routine
Turning prediction into practice does not require a transformation programme. The goal is a routine that fits existing store rhythms, is safe by design, and gets incrementally smarter over time.
The Daily Script
Each morning, an overnight scoring pass produces a short, prioritised list for each store – typically a few dozen items, not hundreds. The list is organised into three lanes: auto-adjust (pre-authorised low-risk corrections within tolerance), quick verify (a brief physical check on borderline items), and count now (Phantom Inventory alerts and non-predictable items).
Teams work the list in order. Phantom Inventory alerts come first: confirm the shelf and backroom, and if empty, immediately set the system stock to zero to release the replenishment order. Capture the reason (misplacement, shrinkage, receiving error, planogram reset). The replenishment cycle is then free to run normally. Quick verifications follow, then low-risk auto-adjustments are applied under lightweight sign-off. At the end of the day, reason codes are logged and feed back into the next scoring cycle.
Who Does What
- Store managers review the daily list, ensure the Phantom Inventory lane is cleared first, and monitor PI trends over time.
- Inventory associates perform the verifications and micro-counts, selecting from a concise reason-code menu.
- Department and category leads apply guardrails appropriate to their categories – tighter tolerances in fresh, wider where audit history shows stability.
- Replenishment and planning monitor recurring patterns – persistent negative stock, unusual point-of-sales signals – and adjust reorder parameters accordingly.
- Loss prevention investigates clusters of positive inaccuracies that suggest receiving errors or systematic misplacements.
- Data and IT maintain the nightly scoring cadence, immutable logs, and quarterly model retraining.
- Finance and Internal Audit sample auto-adjustments and maintain alignment with governance and tax requirements. The ML model does not replace periodic formal audits; rather, it ensures that the routine daily effort conducted between those audits is directed where it matters most.
Tolerance Bands and Department Policy
Every auto-adjustment is bounded by a department-specific tolerance band. Stable ambient packaged goods – where predictability is highest – can accept narrow, automated corrections when both the predictability flag and the driver patterns are normal. Fresh categories default to human verification. The policy implication is straightforward: lower-predictability categories should receive a higher audit cadence, not less attention. The model helps retailers identify where manual counting remains most valuable. In this sense, the system does not only reduce unnecessary checks on stable lines; it actively redirects labour toward the categories where faster intervention is most likely to protect sales and availability. Compliance-sensitive items never auto-adjust. Items outside tolerance require dual approval.
The Phantom Inventory response is explicit and non-negotiable: confirm the shelf and backroom; if empty, set system stock to zero immediately to release replenishment; capture the reason code; and trigger an urgent replenishment or stock transfer. This step costs only minutes, while the sales protected may far exceed that labour cost.
Tuning for Your Business
The operating threshold – how aggressive the model is in flagging items – is “tunable” to each retailer’s priorities. Retailers that are primarily concerned about availability and customer service should set a lower threshold: flag more items, miss fewer problems. Retailers where labour is the binding constraint can raise the threshold: flag only the highest-confidence items, preserve audit minutes. Weekly threshold reviews, using live precision-recall evidence, keep the operating point calibrated as conditions evolve.
The precision-recall trade-off is made visible and configurable. The model produces probability scores, not binary yes/no outputs. This means retailers can set different thresholds for different metric targets: a high-recall setting for Phantom Inventory (catch nearly everything, accept some unnecessary checks) and a high-precision setting for auto-corrections (only adjust when confidence is very high). The choice reflects business strategy, not a technical limitation.
Data You Already Have
The data footprint is intentionally modest. The model requires only data that retail systems already generate: system stock snapshots, audit logs with timestamps, sales and stock movements, price and promotion markers, and product and store master data. No new data collection infrastructure is needed. The main investment is in data quality: reconciling keys across systems, normalising units, and ensuring time-ordering of events.
The 90-Day Path to Deployment
The following Table 6 introduces a possible 90-day path to deploying the solution proposed in this report.
Table 6: The 90-day deployment path.
TimelineActivities
| Weeks 1 – 2 | Align data feeds; validate time ordering and lags; agree reason-code taxonomy with store teams. |
| Weeks 3 – 6 | Feature engineering, predictability screening, initial classifiers; connect to store-tasking tool. |
| Weeks 7 – 10 | Policy tuning: department tolerances, escalation flows, threshold calibration; train associates. |
| Weeks 11 – 13 | Matched test-versus-control pilot: track availability, PI removal, audit productivity, sales impact. |
| Scale | Department-by-department rollout, with thresholds aligned to each retailer’s service and labour priorities. |
Follow-Up: The Test-Versus-Control Experiment
We recommend that each participating retailer run a controlled field experiment as the next step. The design is straightforward: select two matched families of stores – geographically and demographically similar – and assign one group to AI-driven audit allocation based on the model’s daily triage (test stores), while the other continues with traditional counting (control stores). Run the experiment for a fixed period of 4 to 8 weeks, ensuring a statistically significant sample in both groups.
The metrics to track are: on-shelf availability (the ultimate outcome), sales increase attributable to better availability, auditing allocation efficiency (how many checks find a real problem), and Phantom Inventory removal rate. This experiment will quantify the real-world value of prediction before any commitment to full-scale deployment.
Conclusion: A New Era for Stock Counting
Across six grocery retailers and more than 1.3 million stock-audit observations, this research delivers a clear message: a substantial share of inventory record inaccuracy is predictable, and that predictability can be turned into better audit allocation. The staged machine learning pipeline achieves robust Range-1 detection accuracy above 80% across all retailers, precise magnitude corrections for predictable items, and effective Phantom Inventory detection – with results that hold across formats, sizes, and countries.
The operational implications are substantial. Directing scarce store labour to model-identified high-risk items can help retailers address a large share of IRI while protecting availability where it matters most. For Phantom Inventory – the failure mode that silently blocks replenishment and costs sales – the model provides early warning that can eliminate hidden stockouts before customers are affected. Doing all of this without increasing total audit effort is no longer merely aspirational; it is supported by the evidence presented here.
What the model does not yet do. Fresh and process-intensive categories remain more volatile; magnitude corrections should be conservative in these areas until more data accumulates. Data latency, pack-size changes, and planogram resets can temporarily degrade prediction signals – guardrails, immutable logging, and human override remain essential. The economic value estimates presented here are model-based and selection-adjusted rather than direct measurements of realised sales lift; field experiments will quantify actual uplift for each retailer.
What comes next. Integrating richer real-time signals (selective RFID, electronic shelf labels), linking reason codes to error-prevention programmes, and extending the framework to distribution-centre records are all within reach. As digital shelf technology becomes more widespread, the feedback loop between prediction and correction will become faster and richer – making the approach described here increasingly powerful over time.
The implications for stock auditing are clear. Our results provide the opportunity for a better use of limited resources: well-predictable SKUs can be counted less frequently, and the frequency of audits for non-predictable SKUs can be increased. IRI forecasting will not replace traditional stock audits – they will always be needed for taxation purposes and to generate training data for the models. But we now have the tools to complement counting with better prioritisation and more targeted intervention, developing well-thought-out strategies that combine accurate forecasting with targeted inspection.
The evidence presented here supports a disciplined pilot as the appropriate next step.
Six Takeaways for Retail Leaders
- IRI prediction is likely to become an increasingly important part of stock-counting practice. The evidence across six grocery retailers suggests that machine learning can predict inventory discrepancies with operationally useful reliability. For many retailers, the practical question is now less whether to explore this approach than how to test it safely and where to begin.
- Stock counts will not disappear – they will be transformed. The future is intelligent stock count policies that complement traditional counting with prediction, directing physical effort where it is genuinely uncertain.
- Phantom Inventory appears to be the highest-value target. Detecting and correcting it faster than the current audit cycle yields disproportionate service and sales benefits. The model catches over 80% of PI cases, and even false positives tend to be operationally worthwhile checks.
- The predictability filter is the safety cornerstone. Automate where demand dynamics are stable and error patterns consistent; route everything else to human auditing. The predictability filter is designed to reserve automation for cases where the evidence is strongest.
- Non-predictable categories deserve more counting, not less. One of the most important findings is that prediction helps retailers distinguish between stable categories that can be safely deprioritised and volatile categories where more frequent physical verification is likely to deliver the biggest availability and sales benefits.
- Start small and prove the value. A 90-day pilot with matched test-versus-control design will quantify your specific uplift before any commitment to scale.
Appendices
Appendices A to C summarise the scientific backbone of the report in a form suitable for technical reviewers, project sponsors, and retailer data teams. They are intentionally concise: enough to establish methodological rigour, not so detailed that the white paper becomes an academic article. Appendix D introduces a non-technical explanation of how the training, validation, and test sets were designed to reflect real-world decision-making.
Appendix A. Data Structure, Outcome Definitions, and Panel Construction
Each audit observation links a physical count to the system stock position observed immediately before the audit. IRI is defined as physical stock minus system stock. From this discrepancy, the framework derives several targets: generic inaccuracy, tolerance-based exceedance, Physical Zero, and Phantom Inventory. Tolerance-based targets matter because retailers act on materially relevant discrepancies rather than on every non-zero mismatch.
The panel is constructed around audit intervals. For each store-SKU pair, daily sales, replenishment activity, and record behaviour are aligned between consecutive audits, creating a forward-looking feature set that reflects what would have been known before the next count. This design is important because it prevents the model from seeing information that would not have been available at decision time and mirrors the way a retailer would actually deploy the system.
Feature familyExamples of variablesRationale
| Record behaviour and stability | system stock level, share of recent negative or zero values, recent record changes | Persistent instability in the record often signals unreliable transaction capture or drift. |
| Demand pressure | sales since last audit, rolling demand, volatility, sales spikes | Fast depletion and volatile demand increase the chance that book and physical stock diverge. |
| Replenishment execution | deliveries since last audit, time since last delivery, fill-rate proxies | Receiving delays or mismatch between demand and replenishment contribute to record drift. |
| Audit cadence | days since last audit, typical gap between audits, audit regime | Longer intervals allow discrepancies and PI to accumulate. |
| Price and promotion context | promotional flags, price tier, markdown events, listing status | Promotions and price changes elevate demand variability and increase the likelihood of divergence between physical and system stock. |
| Context and lifecycle | department, category, store characteristics, activity flags | Product type and store context explain stable heterogeneity in risk patterns. |
Appendix B. Modelling Pipeline, Leakage Controls, and Probability Calibration
The design uses a staged stacking architecture. Early model heads estimate availability-relevant states such as Physical Zero and Phantom Inventory. A downstream stage models discrepancy severity and tolerance exceedance. A final stage uses original pre-audit features together with upstream out-of-fold risk outputs to estimate overall inaccuracy. This architecture is operationally useful because it creates compact risk summaries that can be used both for prediction and for action prioritisation.
Leakage control is central. Training, validation, and test windows are separated along the time axis. Within training, out-of-fold predictions are generated with chronological rolling-origin folds, meaning each fold is predicted only from earlier data. Validation is then used to calibrate key probabilities before the final untouched test window is assessed. The result is a time-honest estimate of what the model would have done on future data.
Design choiceReason for inclusionImplication
| Time-based splitting | Prevents future audits of the same line from contaminating earlier predictions | Reported performance is forward looking rather than retrospective. |
| Chronological out-of-fold stacking | Avoids in-sample leakage when one model uses another model’s predictions as inputs | Meta-features emulate deployment conditions. |
| Validation-only calibration | Raw probabilities can be poorly aligned with observed frequency | Decision thresholds become interpretable and tunable. |
| Class weighting instead of resampling | Rare events such as PI are important but temporally structured | Imbalance is handled without distorting time order. |
| Strict pre-audit feature set | Post-audit corrections would inflate performance artificially | The model sees only operationally available information. |
Appendix C. Decision Evaluation Under Limited Counting Capacity
The framework is evaluated as a prioritisation policy, not only as a classifier. This distinction is crucial. Stores have fixed daily counting budgets, so the relevant question is how much useful signal the model brings into the first few checks, not whether it can maximise a global metric after the fact. The study therefore reports Top-K and coverage-based capacity-yield curves as the primary decision metrics.
For inaccuracy, those curves show how many genuine problems are surfaced at each counting depth. For Phantom Inventory, they show how quickly record-driven availability risks are concentrated in the ranked list. For severity-oriented policies, they measure how much discrepancy mass above a managerial tolerance is captured as coverage increases. This is the methodological basis for the claim that the same effort can be redirected toward more valuable checks.
Evaluation lensQuestion answered
| Top-K yield | If a store can check only a small number of lines today, how many of those checks will uncover real inaccuracy or PI? |
| Coverage-based yield | As the store increases the fraction of candidate lines checked, how quickly does ranking quality decay toward the base rate? |
| Tolerance-exceedance capture | How much operationally meaningful discrepancy mass is surfaced early in the list? |
| Segmented analysis | Does performance remain useful across audit types, stores, and major categories? |
| Explainability review | Can the drivers of risk be communicated in a way that supports action and trust? |
Methodological payoff
- This decision-oriented evaluation is why the report can talk credibly about counting smarter, not just about predicting better.
Appendix D. How We Tested the System Under Real-World Conditions
Why is this important?
A prediction system can appear highly accurate if it is tested on the same information it was built from. In practice, however, retailers need to know something much more important: Can the system identify tomorrow’s inventory problems before the next audit takes place? To answer that question, we evaluated the models using a forward-looking design that mirrors how the system would operate in a live retail environment. The design principle that splits up the available data into three parts is illustrated in the following figure: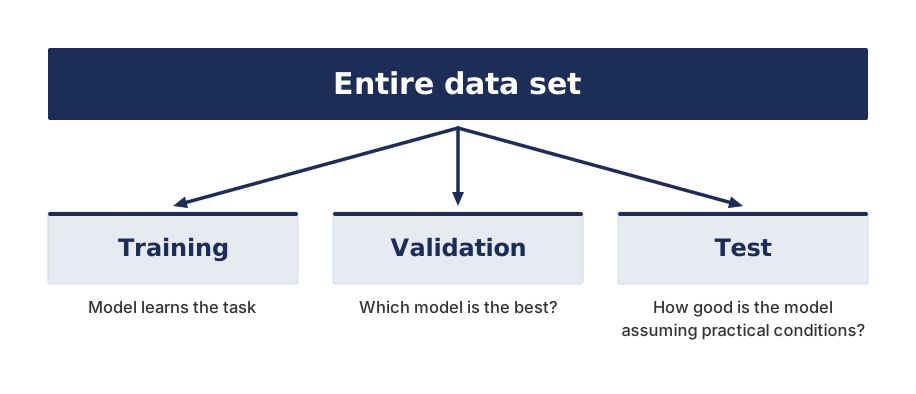
The Principle: Predict the Future, Not the Past
The study covers four years of operational data collected between May 2018 and April 2022. Rather than randomly mixing all observations together, we divided the data according to time. Earlier periods were used to develop the models (training & validation), while later periods were reserved for independent evaluation (test).
The models had access only to information that would have been available in practice at the time a decision was made. Future audit outcomes contained in the test data set were not used during model development. This approach helps answer the practical business question: If the system had been running at the time the test data became available, how well would it have identified inventory discrepancies before the next audit occurred?
Understanding the Three Data Sets
The data were divided into three parts.
- Training Set: The training set contains the earliest historical data. This is the portion used to teach the models patterns associated with future inventory discrepancies. It is comparable to learning from previous audits and historical inventory records.
- Validation Set: The validation set contains a later period that was not used for learning. This portion is used to refine settings and compare alternative model versions. It acts as a rehearsal stage where different approaches can be evaluated before final testing.
- Test Set: The test set contains the most recent period in the data. This portion is kept completely separate until development is finished. It represents future operating conditions that the models have never seen before. It reflects real operating conditions: the data becomes available after the model has been developed, and we can evaluate how well it is able to predict inventory discrepancies that fall into the test period.
All performance results reported in this report are based on this held-out test set. In other words, the reported results reflect performance on future audit events that were unavailable during model development.
What This Means for Retailers
The reported results should not be interpreted as a measure of how well the models can reproduce historical data. Instead, they indicate how effectively the system can prioritise inventory investigations under realistic operating conditions. The evaluation therefore reflects the same decision-making challenge faced by inventory control and loss prevention teams:
- Identify the most likely problem items before the next audit.
- Work within limited labour capacity.
- Focus attention where the expected business impact is highest.
- Avoid relying on information that would not yet be available in practice.
This design provides a conservative but realistic assessment of operational performance.
References
[1] DeHoratius, N.; Raman, A. (2008): Inventory Record Inaccuracy: An Empirical Analysis, Management Science, 54, 627-641. [2] Rekik, Y.; Syntetos, A.A. (2019; Glock, C.H: (2019): Inventory Inaccuracy in Retailing: Does it Matter? [3] Yun, K.; Gershwin, S.B. (2005): Information inaccuracy in inventory systems: stock loss and stockout, IIE Transactions, 37, 843-859. [4] Rekik, Y.; Syntetos, A.A.; Glock, C.H. (2019): Modeling (and Learning from) Inventory Inaccuracies in E-retailing/B2B contexts, Decision Sciences, 50, 1184-1223. [5] Chuang. H.H.-C.; Oliva, R. (2015): Inventory record inaccuracy: Causes and labor effects, Journal of Operations Management, 39-40, 63-78. [6] Chen, L. (2021): Fixing Phantom Stockouts: Optimal Data-Driven Shelf Inspection Policies, Production and Operations Management, 30, 689-702. [7] Best, J.; Glock, C.H.; Grosse, E.H.; Rekik, Y.; Syntetos, A.A. (2022): On the causes of positive inventory discrepancies in retail stores, International Journal of Physical Distribution & Logistics Management, 52, 414-430. [8] Glock, C.H.; Syntetos, A.A.; Rekik, Y. (2025): Defining and assessing inventory record inaccuracy. [9] Glock, C.H.; Syntetos, A.A.; Rekik, Y. (In Press): On the measurement of inventory record inaccuracies, The International Review of Retail, Distribution and Consumer Research. [10] Opitz, D.; Maclin, R. (1999): Popular Ensemble Methods: An Empirical Study, Journal of Artificial Intelligence Research, 11, 169-198. [11] Powers, D.M. (2011): Evaluation: From Precision, Recall and F-Factor to ROC, Informedness, Markedness & Correlation, Journal of Machine Learning Technologies, 2, 37-63. [12] Hart, S. (1989): Shapley Value, in: The New Palgrave: Game Theory, J. Eatwell, M. Milgate und P. Newman (Eds.), Norton, Springer Nature, pp. 210-216.Notes
- A staged ensemble learning approach in machine learning involves a series of stages where multiple models are trained and combined to improve predictive performance. The method is particularly useful when individual models may have different strengths and weaknesses. For further information on ensemble learning, please refer to [10].
- For an overview and discussion of alternative ways of measuring inventory record inaccuracy, please refer to [8, 9].
- Precision measures how accurate positive predictions are, while recall measures how many actual positives are correctly identified. So, the former is the proportion of positive predictions that are actually correct. In other words, it answers the question: “Of all the items the predicted as positive, model how many truly are positive?” High precision means the model makes few false positive errors. The latter is the proportion of actual positive cases that the model correctly identifies. It answers: “Of all the real positive items, how many did the model find?” High recall means the model misses very few true positives. Often, increasing one reduces the other, so a balance is needed depending on the application. For further information on evaluation measures for machine learning, including precision and recall, please refer to [11].
- SHAP (Shapley Additive Explanations) is a method that quantifies the contribution of each feature to a machine learning model’s prediction using principles from game theory. For further information on the SHAP value, please refer to [12].
Disclaimer
The research for this report was supported by ECR Retail Loss. The report is intended for general information only; it is based upon a review of the available literature together with original research undertaken with retail organisations worldwide. Individuals or companies are advised to seek professional guidance regarding their specific needs prior to taking any actions resulting from anything contained in this report.
About the Authors
Yacine Rekik is Professor of Operations & Supply Chain Management at emlyon business school, France. His research develops models that provide qualitative and quantitative insights into the impact of inventory inaccuracies and the benefits of RFID technology on supply chain performance. Contact: yrekik@em-lyon.com
Aris A. Syntetos is Distinguished Research Professor of Decision Science and the DSV Chair of Logistics at Cardiff Business School, Cardiff University. He researches forecasting and uncertainty management for improving inventory and supply chain decisions. Contact: aris@cardiff.ac.uk
Christoph H. Glock is Head of the Institute of Production and Supply Chain Management at Technical University of Darmstadt, Germany. His research concentrates on the coordination of inventory replenishments and the management of physical stocks. Contact: glock@pscm.tu-darmstadt.de
Acknowledgements
Research commissioned by ECR Retail Loss is made possible by independent research grants provided by Axon Checkpoint Systems, NCR Voyix, Retail Insight, RGIS and Vusion.
[GALLERY PLACEHOLDER: sponsor logos — Axon Checkpoint Systems, NCR Voyix, Retail Insight, RGIS, Vusion]About ECR Retail Loss
ECR Retail Loss is part of ECR Community, a voluntary and collaborative retailer-manufacturer platform with a mission to fulfil consumer wishes better, faster and at less cost. Over the last 26 years, the ECR Retail Loss Working Group has acted as an independent think tank focused on creating imaginative new ways to better manage the problems of loss and on-shelf availability across the retail industry. Championing the idea of Sell More and Lose Less, ECR Retail Loss is open for any retailer and manufacturer to join at no cost.
For further information: https://www.ecrloss.com/


